Delivered online or onsite, our instructor-led PySpark training programs provide hands-on experience in leveraging Python and Spark to process and analyze big data.
PySpark instruction is offered as "online live training" or "onsite live training." Online sessions (also referred to as "remote live training") are facilitated through an interactive remote desktop. Onsite training can be hosted locally at customer facilities in Nantes or within NobleProg corporate training centers in Nantes.
NobleProg -- Your Local Training Provider
Nantes, Zenith
NobleProg Nantes, 4 rue Edith Piaf, Saint-Herblain, france, 44821
In the Parc d'Ar Mor zone, near the Zénith.
Car : from the ring road, Porte de Chézine Exit> Boulevard du Zenith > Esplanade Georges Brassens (restaurants) > Rue Edith Piaf on the right. From the N444 road (Nantes > Lorient), Exit #1 > boulevard Marcel Paul > Rue Edith Piaf at the right.
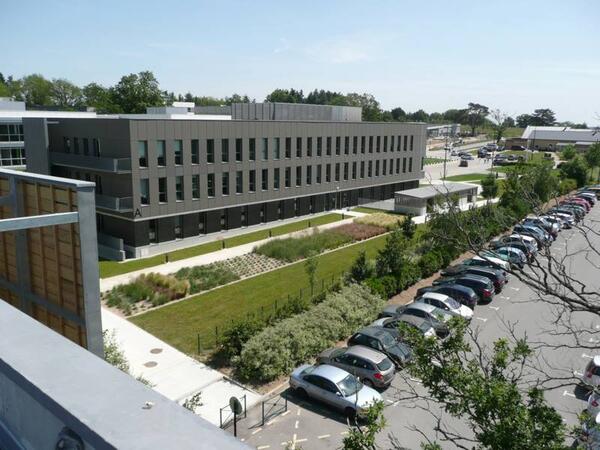
Parking Zénith P1 (free). Once parked, you can recognize the building: it's one of the tree bulding with zinc frontage.
Bicycle: free indoor parking
Public transport :
Tramway R1, Schoelcher station + 10 mn by foot through commercial center Atlantis
Tramway R1, François Mitterrand stop + bus 50, stop at Saulzaie station or bus 71, stop at the Zénith station
Tramway R3, Marcel Paul station + bus 50, Saulzaie station
Chronobus C6, Hermeland station+ bus 71, Zénith station
Bus : lignes 50 (Saulzaie station) or 71 (Zénith station)
This instructor-led live training in Nantes delves into the Stratio platform, with a specific focus on the Rocket and Intelligence modules using PySpark. Participants will gain mastery over data ingestion, transformation, and advanced analytics, while developing practical skills in loops, UDFs, and enterprise data workflows.
This instructor-led, live training in Nantes guides participants in harnessing the power of Python and Spark to analyze big data, supported by engaging hands-on exercises.
By the end of the session, participants will be able to:
Utilize Spark and Python together for effective big data analysis.
Complete exercises that simulate real-world professional challenges.
Employ various tools and techniques for big data analytics via PySpark.
This instructor-led live training (available online or onsite) is designed for data engineers, analysts, and professionals seeking to use Databricks and PySpark to build scalable data pipelines and migrate existing SQL workflows.
This course offers a hands-on introduction to creating scalable data processing and Machine Learning workflows with PySpark. Attendees will discover how Apache Spark functions within contemporary Big Data ecosystems and how to effectively manage large datasets by applying distributed computing principles.
This three-day practical course focuses on building and optimising efficient data-processing workloads using PySpark, Pandas and Polars in Kubernetes-based environments.
Participants will develop a practical understanding of how Spark applications execute on Kubernetes and how application-level configuration decisions influence performance, scalability, resource consumption and cost. The course covers key optimisation areas including executor sizing, memory allocation, dynamic allocation, partitioning strategies, shuffle behaviour, small-file problems and efficient Parquet processing.
The course also addresses common challenges when working with Pandas, including memory limitations and out-of-memory failures, and introduces Polars as a high-performance alternative for selected data-processing workloads. Through hands-on exercises, participants will diagnose performance and memory issues, compare different configuration strategies and apply optimisation techniques to realistic ETL and machine learning scenarios.
The emphasis throughout the course is on practical decision-making: understanding how to identify bottlenecks, select the appropriate tool, configure Spark efficiently and balance performance with infrastructure resource consumption and cost.
Read more...
Last Updated:
Testimonials (2)
Showing different ways to optimize our PySpark queries.
Ivan Abrashev - UBB + DZI (KBC GROUP)
Course - Efficient Data Processing on Kubernetes with PySpark, Pandas & Polars
I liked that it was practical. Loved to apply the theoretical knowledge with practical examples.
Online PySpark training in Nantes, PySpark training courses in Nantes, Weekend PySpark courses in Nantes, Evening PySpark training in Nantes, PySpark instructor-led in Nantes, PySpark on-site in Nantes, Weekend PySpark training in Nantes, PySpark coaching in Nantes, PySpark trainer in Nantes, PySpark boot camp in Nantes, Online PySpark training in Nantes, PySpark instructor-led in Nantes, Evening PySpark courses in Nantes, PySpark classes in Nantes, PySpark instructor in Nantes, PySpark private courses in Nantes, PySpark one on one training in Nantes